TSMC’s CoWoS Capacity to Double by 2028—and Rivals Will Still Win Orders

TSMC’s CoWoS Capacity to Double by 2028—and Rivals Will Still Win Orders
by Daniel Nenni on 09-18-2026 at 8:00 am

TSMC’s CoWoS Capacity to Double by 2028—and Rivals Will Still Win Orders

TSMC reportedly plans to double its Chip-on-Wafer-on-Substrate capacity from approximately 130,000 300mm-equivalent wafers per month at the end of 2026 to 260,000 by 2028. The estimate is not formal company guidance and should be treated as a supply-chain projection. Nevertheless, the direction is consistent with TSMC’s aggressive investment in advanced packaging and indicates that artificial-intelligence infrastructure demand is evolving from a temporary shortage into a multiyear capacity cycle.

CoWoS is a family of 2.5D packaging technologies that places logic dies—such as GPUs or custom accelerators—and high-bandwidth memory on a silicon interposer or redistribution-layer structure. The components communicate through dense, short interconnects before the assembly is mounted on an organic substrate. Compared with routing signals across a conventional circuit board, this architecture provides much higher bandwidth, lower latency and better energy efficiency.

That makes advanced packaging essential to AI performance. Leading accelerators require several HBM stacks to keep thousands of compute units supplied with data. A faster processor has limited value if memory bandwidth, interconnect density or power delivery cannot scale with it. CoWoS therefore is not simply the final step after wafer fabrication; it increasingly determines how much useful compute can be extracted from leading-edge silicon.

Package dimensions are also expanding. TSMC says it certified a CoWoS solution supporting interposers measuring 5.5 times the maximum mask or reticle area in 2025, with volume production planned for 2026. Larger packages can accommodate more compute chiplets, input/output dies and HBM stacks, but they consume more interposer area and packaging resources per device. Consequently, doubling wafer-equivalent capacity does not necessarily double the number of completed accelerators. TSMC’s 2025 annual report also identifies CoWoS, InFO and SoIC as central technologies for large-scale, power-efficient integration.

The expansion should help Nvidia, AMD and custom-ASIC developers raise shipments, yet it may not eliminate the shortage. AI clusters are moving toward larger multi-die packages, while hyperscalers are developing internal accelerators alongside purchases of merchant GPUs. Demand is therefore increasing in both volume and packaging intensity. Yield management, HBM availability, substrates, thermal solutions and testing capacity can remain bottlenecks even when nominal CoWoS output rises.

This imbalance creates an opening for Intel Foundry. Intel’s Embedded Multi-die Interconnect Bridge places small silicon bridges inside the package substrate instead of using a large interposer beneath every die. Foveros adds vertical die stacking, while EMIB-T combines bridge-based connections with through-silicon vias for improved signal and power delivery. These technologies are not drop-in replacements for every CoWoS design; customers must qualify physical interfaces, assembly processes, thermal behavior and reliability. But they offer an alternative route for new custom accelerators. Intel has confirmed that its advanced-packaging portfolio includes EMIB, EMIB-T and Foveros, while MediaTek has publicly said it supports both Intel and TSMC packaging platforms.

Outsourced semiconductor assembly and test providers should capture spillover as well. ASE, Amkor and other OSAT companies can perform portions of package assembly, bumping, substrate integration and final testing, either through cooperation with foundries or through competing 2.5D platforms. Amkor’s Arizona advanced-packaging campus, scheduled to begin production in 2028, illustrates how packaging demand is also encouraging geographic diversification.

Bottom line: Semiconductor leadership is no longer defined solely by transistor density. The ability to combine heterogeneous dies, HBM and high-speed interfaces at acceptable yield and cost now determines accelerator supply. TSMC’s expansion reinforces its leadership, but persistent demand gives Intel and OSAT providers something equally valuable—production orders, customer qualifications and the opportunity to become permanent second sources rather than temporary overflow suppliers.

We will get an update next week at the TSMC OIP Forum but this is where we are at today. Simply incredible, absolutely.

Also Read:

TSMC’s 2026 OIP Forum to Spotlight the Technologies Shaping the Next Era of Chips

Comparing Advanced Packaging from TSMC, Intel Foundry, and Samsung Foundry

Comparing Intel EMIB and Intel Foveros


TSMC’s 2026 OIP Forum to Spotlight the Technologies Shaping the Next Era of Chips

TSMC’s 2026 OIP Forum to Spotlight the Technologies Shaping the Next Era of Chips
by Daniel Nenni on 09-11-2026 at 6:00 am

TSMC OIP 2026

It’s that time of year again. Time certainly flies when AI is chasing you! This year marks the 18th TSMC OIP Ecosystem Forum, and it promises to be bigger and better than ever. My SemiWiki partners, Mike Gianfagna and Kalar Rajendiran, will join me in covering the event live, so stay tuned for all the news that’s fit to print.

Mike and Kalar previously worked at eSilicon, which was both a major SemiWiki sponsor and a TSMC Value Chain Aggregator. Kalar also manages the SemiWiki IP Reports. It really is a small semiconductor world.

TSMC will bring together semiconductor designers, technology partners, customers, analysts and media for its 2026 North America Open Innovation Platform Ecosystem Forum on Wednesday, September 23, at the Santa Clara Convention Center in California. Running from 9 a.m. to 2:30 p.m. Pacific Time, the event will examine how advances in silicon processes, chip packaging, artificial intelligence and electronic design tools are changing the way increasingly complex integrated circuits are built.

The forum’s theme, “Expanding AI with Leadership Ecosystem,” reflects the growing importance of collaboration across the semiconductor industry. Modern chips are no longer created through manufacturing innovation alone. Their development depends on a closely connected network of foundries, design-software providers, intellectual-property suppliers, cloud platforms, packaging specialists and customers. TSMC’s Open Innovation Platform, or OIP, is intended to bring those capabilities together and make them available through validated, production-ready design solutions.

Next-generation process technology will be a central topic. Presentations will cover design flows, methodologies and tools supporting TSMC’s N2, A16 and A14 processes, with particular attention to energy efficiency, multiphysics effects and advanced chip architectures. Attendees will also receive updates on the continuing development of tools and solutions for established and forthcoming advanced nodes, including N3, N2 and processes beyond them.

Advanced packaging will receive comparable attention. The program will explore design solutions for TSMC’s 3DFabric portfolio, including InFO, CoWoS, SoIC and SoW technologies, as well as TSMC-COUPE. These technologies allow companies to combine multiple computing, memory and connectivity components within sophisticated packages or three-dimensional systems. This approach has become increasingly important as developers seek higher performance without depending exclusively on traditional transistor scaling.

The forum will also examine the use of agentic AI in semiconductor design. TSMC’s ecosystem partners are expected to demonstrate how more autonomous AI workflows can improve productivity and optimize both conventional two-dimensional chips and complex 3D integrated circuits. Additional sessions will address solutions tailored to high-performance computing, AI and machine learning, automotive systems, mobile devices and the Internet of Things. Specialty platforms covering ultra-low-power, ultra-low-voltage, analog, radio-frequency and millimeter-wave technologies will round out the technical program.

The agenda begins with registration and breakfast at 8:30 a.m., followed by welcome remarks at 9:30. TSMC keynotes and a guest speech will run until 11 a.m. Afterward, TSMC and OIP partners will lead technical sessions. The event also includes the OIP Partner of the Year Award luncheon and an afternoon visit to the ecosystem pavilion, where participants can examine partner technologies and solutions. Customer case studies will illustrate how collaboration, semiconductor IP and cloud-based design environments can shorten development cycles and accelerate products’ arrival in the market.

Why does this matter? The semiconductor industry is confronting several challenges at once. AI systems require enormous increases in computing and memory performance, but power consumption, heat, manufacturing complexity and development costs are also rising. No single company can solve all of those problems independently. Progress increasingly depends on whether manufacturing processes, design tools, reusable IP and advanced packaging technologies work together reliably.

The OIP Forum therefore serves as more than a showcase for individual technologies. It offers a view of whether the broader design ecosystem is ready to turn ambitious process and packaging roadmaps into manufacturable products. Updates involving N2, A16 and A14 may help indicate how designers will access future gains in performance and efficiency. Developments around CoWoS, SoIC and other 3DFabric technologies are especially relevant to AI accelerators, where closely integrating processors and high-bandwidth memory has become critical.

Bottom line: The attention given to agentic AI is equally significant. If these workflows prove dependable, they could help engineering teams explore more design options, identify problems earlier and manage the growing complexity of 2D and 3D systems. Ultimately, the forum matters because the innovations discussed there may influence the cost, speed and energy efficiency of future computing products—from data-center AI hardware and vehicles to smartphones and connected devices.

Also Read:

TSMC’s Overseas Fabs Are Paying Off

How TSMC Is Wiring the AI Era With Light

A 0.42-Nanometer Breakthrough From TSMC Could Push Transistors Beyond Silicon


ASML and TSMC’s 12-Inch Photomask Initiative: Technical Significance

ASML and TSMC’s 12-Inch Photomask Initiative: Technical Significance
by Daniel Nenni on 09-07-2026 at 11:00 pm

ASML and TSMC’s 12 Inch Photomask Initiative

ASML and TSMC’s proposed shift from 6-inch to 12-inch photomasks is an attempt to redesign a critical but often overlooked part of advanced semiconductor manufacturing. Photomasks are precision plates carrying the circuit patterns projected by a lithography scanner onto a silicon wafer. In extreme-ultraviolet lithography, 13.5-nanometer light reflects from a multilayer mask, passes through the scanner’s projection optics, and prints features in photoresist. Mask quality, size, flatness, defect control, and pattern placement therefore directly affect yield and productivity.

The initiative is tied to High Numerical Aperture EUV, or High NA EUV. Numerical aperture determines how much light an optical system can collect and how finely it can resolve features. ASML’s High NA platform increases NA from 0.33 in conventional EUV systems to 0.55, enabling smaller printed features and reducing the need for costly multiple-patterning steps. However, High NA optics use anamorphic imaging: the pattern is demagnified differently in the scan and non-scan directions. This design controls mirror size but reduces the exposure field available from today’s 6-inch masks.

A smaller effective field creates a practical constraint for large chips. If a design exceeds the field, the scanner must expose separate sections and “stitch” them together on the wafer. Stitching can enable large processors, especially AI accelerators, but it adds design rules, alignment requirements, process complexity, and potential yield risk at the seam. A 12-inch mask offers substantially more pattern area. The larger format could restore or expand the usable field, reducing stitching and allowing more dies, or larger dies, to be exposed efficiently.

The productivity argument is equally important. Lithography tools are among the most expensive and capacity-sensitive assets in a leading-edge fab. A larger mask could contain more exposure content and reduce mask swaps, stage movements, or the number of exposure sequences required for some layouts. Any improvement in wafers per hour spreads scanner depreciation and operating expense across more good chips. That can lower cost per transistor even when the capital cost of High NA systems is exceptionally high.

The transition is not a simple scale-up. A 12-inch EUV mask demands new blanks, substrates, reflective coatings, absorbers, pattern-writing tools, inspection systems, cleaning equipment, handling robots, pellicles, storage containers, and scanner interfaces. Larger masks will be heavier and harder to keep flat, while tiny distortions or particles can print systematic defects across many wafers. The entire metrology and logistics chain must meet nanometer-level tolerances. This explains why ASML and TSMC are organizing an industry-wide initiative years before production: no scanner manufacturer, foundry, mask shop, or materials supplier can create the standard alone.

The announced schedule reflects that systems challenge. TSMC intends to introduce High NA EUV into high-volume manufacturing for advanced nodes beginning in 2030, initially with existing 6-inch masks. The partners target a 12-inch mask pilot line by 2031 and production-ready 12-inch High NA lithography by 2033. This staged approach separates adoption of the new optics from adoption of the new mask infrastructure, reducing the risk of changing both simultaneously.

For chip designers, the benefit could appear as fewer floor-planning compromises and greater freedom to build large compute engines. For equipment suppliers, it creates a demanding development roadmap and a potential new market. For governments, it highlights how semiconductor leadership depends on coordinated, long-horizon investment across a concentrated supply chain.

Bottom line: First, it signals that High NA EUV is moving from a resolution experiment toward an industrial production platform. Second, it anticipates AI-driven transistor architectures with more layers requiring the technology. Third, it seeks to preserve scaling economics: finer features are valuable only if manufacturers can print them at high yield and competitive throughput. Finally, the initiative could establish a new ecosystem standard, creating large investment opportunities but also reinforcing the strategic importance of ASML, TSMC, and specialized suppliers. The real breakthrough is therefore not merely a bigger mask. It is coordinated infrastructure intended to make the next generation of advanced chips manufacturable at scale.

Source: 

Also Read:

Comparing Advanced Packaging from TSMC, Intel Foundry, and Samsung Foundry

TSMC’s Overseas Fabs Are Paying Off

How TSMC Is Wiring the AI Era With Light


Comparing Advanced Packaging from TSMC, Intel Foundry, and Samsung Foundry

Comparing Advanced Packaging from TSMC, Intel Foundry, and Samsung Foundry
by Daniel Nenni on 09-06-2026 at 10:00 am

Advanced Chip Packaging Comparison INtel TSMC Samsung

Advanced semiconductor packaging has become essential to improving computing performance as conventional transistor scaling grows more difficult and expensive. Instead of manufacturing an entire processor as one large monolithic die, chipmakers can divide it into smaller chiplets and combine logic, memory, input/output and specialized accelerators within one package. TSMC, Intel Foundry and Samsung Foundry all offer technologies for this purpose, but their portfolios differ in architecture, maturity, market position and integration strategy.

TSMC groups its advanced packaging technologies under the 3DFabric platform. Its principal offerings are CoWoS, InFO and SoIC. CoWoS, or Chip-on-Wafer-on-Substrate, is primarily a 2.5D technology for high-performance computing and artificial intelligence. It places logic dies and high-bandwidth memory, or HBM, on an interposer that provides dense, high-speed connections. CoWoS-S uses a silicon interposer, while CoWoS-L combines local silicon interconnects with a redistribution-layer structure. CoWoS-R relies more extensively on redistribution layers to provide a cost-conscious option for suitable designs.

CoWoS has become especially important for large AI accelerators, where several HBM stacks must communicate with GPUs or custom processors at enormous bandwidth. TSMC says CoWoS-S supports silicon interposers up to approximately 3.3 times the lithographic reticle size, while CoWoS-L and CoWoS-R address larger configurations. TSMC’s InFO family provides fan-out packaging without a conventional silicon interposer and is used where thin profiles, efficient wiring and lower cost are priorities. SoIC addresses true three-dimensional integration by directly stacking dies with dense vertical connections. SoIC stacks can also be incorporated into CoWoS or InFO packages, creating what TSMC calls a “3Dx3D” system. TSMC 3DFabric overview

Intel Foundry’s portfolio centers on EMIB and Foveros. EMIB, or Embedded Multi-die Interconnect Bridge, connects chiplets positioned side by side through small silicon bridges embedded in the organic package substrate. Unlike a full silicon interposer, EMIB places silicon only where dense die-to-die communication is needed. This can reduce silicon usage, simplify some aspects of assembly and allow designers to construct packages larger than a single reticle. EMIB is well suited to connecting compute tiles, I/O dies and HBM while leaving each component relatively accessible for cooling.

Foveros complements EMIB by supporting vertical integration. In a Foveros package, compute chiplets can be stacked on an active base die that provides communication or other functions. Foveros Direct uses copper-to-copper hybrid bonding to obtain finer connection pitches, lower resistance and greater bandwidth between stacked dies. Intel can combine Foveros stacks with EMIB bridges in an EMIB 3.5D package, gaining both vertical density and horizontal scalability. Intel is also expanding the portfolio with variants such as EMIB-T, which adds through-silicon vias, and Foveros-R, a redistribution-layer option intended to balance cost and performance. Intel Foundry packaging overview

Samsung Foundry offers comparable horizontal and vertical integration technologies. Its current horizontal portfolio includes 2.5D Cube-S and 2.3D Cube-E and Cube-R. Cube-S, previously associated with Samsung’s I-Cube naming, places logic chips and HBM on a silicon interposer. Samsung says qualified configurations can use a 3.3-reticle-size interposer and integrate up to eight HBM modules, with larger options supporting additional memory. Cube-E uses embedded silicon bridges, making it conceptually similar to Intel EMIB, while Cube-R employs a redistribution-layer interposer.

For vertical integration, Samsung offers 3D Cube technologies, formerly called X-Cube. The 3D Cube-T variant uses thermo-compression bonding in a chip-on-wafer process, while 3D Cube-H uses hybrid copper bonding for finer pitches and improved electrical performance. These technologies stack dies to shorten communication paths, save package area and reduce the yield risks associated with extremely large monolithic chips. Samsung’s broader strength is its ability to combine foundry manufacturing, packaging and memory expertise within one company—an attractive proposition for systems that depend heavily on HBM. Samsung Foundry packaging overview

Technically, the three companies are converging on similar categories. TSMC CoWoS-S and Samsung Cube-S use large silicon interposers for 2.5D integration. Intel EMIB and Samsung Cube-E use localized embedded bridges instead of full interposers. TSMC SoIC, Intel Foveros Direct and Samsung 3D Cube-H pursue dense vertical stacking through advanced bonding. Each vendor also offers redistribution-layer alternatives that can reduce cost where maximum silicon-interposer density is unnecessary.

Their main differences lie in execution and ecosystem. TSMC benefits from its position as the leading manufacturer of advanced chips for numerous fabless customers, giving 3DFabric and CoWoS a powerful customer base and extensive exposure to AI products. Intel brings long experience packaging its own complex processors and emphasizes flexible bridge-based integration, large package sizes and geographically distributed assembly capabilities. Samsung offers a vertically integrated route connecting logic fabrication, advanced packaging and memory production, although customers must evaluate its particular process maturity, design ecosystem, capacity and product requirements.

Bottom line: There is no universally superior portfolio. TSMC is especially prominent in interposer-based AI packaging; Intel differentiates itself through EMIB and combined 3.5D architectures; and Samsung offers a broad, increasingly unified set of interposer, bridge and vertical-stacking technologies. The correct choice depends on bandwidth, thermal limits, HBM count, chiplet sources, package size, production capacity, cost and supply-chain strategy.

Also Read:

Intel and TSMC Take Different Paths to High-NA EUV

Intel Foundry and the DAC2026 Ecosystem

Executive Interview with James Huang of AlChip


TSMC’s Overseas Fabs Are Paying Off

TSMC’s Overseas Fabs Are Paying Off
by Daniel Nenni on 08-28-2026 at 6:00 am

TSMC's Overseas Fabs Are Paying Off

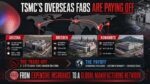
TSMC’s overseas fabrication strategy is beginning to deliver its intended return: not immediate cost parity with Taiwan, but manufacturable geographic redundancy, closer integration with major customers and access to subsidized capacity in strategically important markets. Arizona and Kumamoto are already producing commercially, while Dresden extends the model into Europe’s automotive semiconductor ecosystem.

The clearest validation is Arizona’s Fab 21. Its first phase entered high-volume production on the N4 process in the fourth quarter of 2024, achieving yields comparable with TSMC’s Taiwanese fabs. Yield parity matters because advanced-node economics are extremely sensitive to defect density. A foreign fab that requires substantially more wafer starts per functional die would provide political resilience but destroy economic value. Arizona has crossed that technical threshold.

Demand is also materializing. Apple, the fab’s first and largest customer, expects to purchase well over 100 million advanced chips from the facility in 2026—a significant increase from 2025. AMD has likewise identified Arizona as a source of leading-edge products. TSMC has therefore accelerated its second Arizona fab, now scheduled for high-volume manufacturing in the second half of 2027. That facility will introduce 3-nanometer-class production, while subsequent fabs are planned for N2, A16 and later technologies. The objective is no longer an isolated factory; it is an independent “GIGAFAB” cluster incorporating wafer fabrication, advanced packaging and research capabilities. (TSMC, Apple)

Kumamoto demonstrates a complementary localization model. Japan Advanced Semiconductor Manufacturing, TSMC’s venture with Sony, Denso and Toyota, began volume production in late 2024 with what TSMC describes as very good yield. Its initial 12/16-nanometer and 22/28-nanometer processes serve image sensors, automotive controllers and industrial devices—markets where supply continuity, qualification history and proximity to customers can be more valuable than transistor density. A second Kumamoto fab is under construction, and TSMC now plans to introduce 3-nanometer technology there in response to AI-related demand. This converts Japan from a specialty-node outpost into a potential advanced-logic base.

Dresden completes the regional segmentation. European Semiconductor Manufacturing Company, owned by TSMC, Bosch, Infineon and NXP, is designed around 300-millimeter automotive and industrial production rather than leading-edge AI accelerators. Its technology portfolio and local joint-venture structure reduce qualification and logistics risks for European customers. Germany’s €5 billion state-aid package offsets part of the structural cost disadvantage of manufacturing in Europe. (European Commission)

The payoff should not be confused with near-term margin accretion. Labor, construction, utilities, supplier density and smaller initial scale make overseas wafers more expensive. TSMC forecasts that foreign-fab ramp-ups will dilute gross margin by two to three percentage points in their early stages and by three to four points later as expansion accelerates. Nevertheless, the company posted a 59.9% gross margin in 2025, suggesting that leading-edge demand, utilization and pricing can absorb the burden. (TSMC Q2 2026)

Bottom Line: The strategic return is therefore risk-adjusted rather than purely accounting-based. Subsidies lower capital intensity; customer commitments improve utilization visibility; replicated process control proves that TSMC’s manufacturing system can travel; and regional capacity reduces exposure to earthquakes, shipping disruptions and geopolitical concentration. Taiwan will remain the center of TSMC’s newest technology and largest scale. But overseas fabs are evolving from expensive insurance policies into productive, customer-backed nodes of a global manufacturing network—and that is precisely how the investment begins to pay off.

Also Read:

How TSMC Is Wiring the AI Era With Light

A 0.42-Nanometer Breakthrough From TSMC Could Push Transistors Beyond Silicon

Intel and TSMC Take Different Paths to High-NA EUV


How TSMC Is Wiring the AI Era With Light

How TSMC Is Wiring the AI Era With Light
by Daniel Nenni on 08-21-2026 at 10:00 am

How TSMC Is Wiring the AI Era With Light

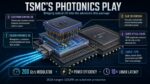
TSMC’s photonics strategy is centered on integrating optical input-output with advanced logic, rather than selling conventional optical transceivers as standalone products. The company is developing a silicon-photonics foundry platform and a packaging architecture called TSMC-COUPE, or Compact Universal Photonic Engine, aimed primarily at AI and high-performance-computing interconnects.

A silicon-photonics die implements optical waveguides, modulators, photodetectors and fiber-coupling structures using semiconductor manufacturing techniques. However, it still requires electronic circuitry for modulation drivers, receiver amplification, clocking and control. In many optical modules, the electronic integrated circuit and photonic integrated circuit are separate dies connected laterally or through package wiring. Those connections add parasitic resistance, capacitance and inductance, increasing power and limiting signaling speed.

COUPE addresses that interface by vertically stacking an electronic die on a photonic die with TSMC’s SoIC chip-on-wafer bonding technology. Fine-pitch, high-density connections shorten the electrical path between driver or receiver circuits and optical devices. TSMC says the structure supports both grating and edge fiber couplers while avoiding cavities and mechanically weak features. The optical engine can then be integrated beside a host ASIC in a larger package.

TSMC has pursued a staged commercialization plan. The first implementation targeted small-form-factor pluggable optics, providing a lower-risk environment for process qualification, device characterization, assembly and reliability testing. The next step is true co-packaged optics, or CPO, in which the optical engines move from the circuit board into the switch or compute package. TSMC announced that a COUPE-on-substrate CPO solution is entering production in 2026.

The company reports that in-package COUPE provides twice the power efficiency and one-tenth the latency of a pluggable board-level implementation. Its platform includes a 200-gigabit-per-second micro-ring modulator, a compact resonant device that converts an electrical data stream into optical modulation. TSMC’s 2025 reporting also says it achieved 200-gigabit-per-second operation with multiple customers and is developing CPO to reduce data-center data-movement energy by more than 50 percent.

Photonics is being tied directly to TSMC’s 3DFabric portfolio. SoIC supplies vertical die-to-die integration; CoWoS can combine optical engines, switch or accelerator ASICs, chiplets and high-bandwidth memory on an interposer and substrate. This is strategically important because an optical link cannot be optimized independently of SerDes circuits, package routing, power delivery, cooling, fiber attachment and test. TSMC can co-design those interfaces while using manufacturing infrastructure already developed for large AI packages.

The immediate application is scale-out networking between racks and potentially scale-up connectivity among accelerators. Electrical channels become progressively harder to drive as data rates and distances increase: insertion loss rises, equalization grows more complex, and retimers consume additional power. Moving the electro-optical conversion closer to the ASIC reduces the length of high-speed copper channels. Optical fiber then carries bandwidth over distance with lower loss.

Significant challenges remain. Micro-ring modulators are compact and efficient but sensitive to fabrication variation and temperature, requiring wavelength control. External lasers must deliver stable optical power without creating thermal or reliability problems inside the package. Fiber attach demands micrometer-scale alignment, while known-good-die screening, optical testing, repairability and yield become difficult when expensive logic and photonics are combined. CPO also changes field service: a failed optical engine cannot be replaced as easily as a pluggable transceiver.

TSMC is separately researching more ambitious photonic computing. It has reported a wafer-integrated digital optical computing system using multilayer photonic fan-out and stacked electronic-photonic dies, with less than 0.08 picojoules per multiply-accumulate operation in an eight-bit, 512-by-512 demonstration. That work is exploratory, whereas COUPE is the near-term commercial focus.

Bottom line: TSMC is treating photonics as a system-integration problem. Its competitive asset is not any single modulator or waveguide. It is the ability to combine a qualified photonics process, electronic control silicon, three-dimensional bonding, interposers, advanced packaging and high-volume manufacturing into a customer-ready platform. That positioning lets fabless chip companies adopt optical connectivity without building their own photonics factories or assembling a fragmented supply chain. If production scales, TSMC could make optical I/O a standardized extension of leading-edge chip design and packaging.

Also Read:

A 0.42-Nanometer Breakthrough From TSMC Could Push Transistors Beyond Silicon

Intel and TSMC Take Different Paths to High-NA EUV

The Difference Between TSMC CoWoS-S and CoWoS-R

TSMC CoPoS Versus Intel EMIB Semiconductor Packaging


The Twelve-Month Rule Does Not Describe a New Fab

The Twelve-Month Rule Does Not Describe a New Fab
by Admin on 08-20-2026 at 10:00 am

capex to wafer starts lag

By Nikhil Shah

Capital spending is often treated as if it becomes semiconductor capacity about twelve months later. That can be a useful rule for equipment installed in an existing fab. It is a poor description of a new fab built from the ground up.

I tested the distinction using five advanced-node projects in the United States where I could source both a construction start and a first-production date. The set covers TSMC, Intel, Samsung and Micron. Measured from the start of construction to first production, the disclosed schedules have a median lag of 45 months and a range of 39 to 60 months.

That is not a new industry rule. Five projects are too few, several dates are only precise to a year, and three of the production dates were still targets as of August 2026. It does show why a twelve-month capex lag and a four-year fab schedule can both be true.

Two different clocks

The shorter clock starts after the shell, cleanroom, utilities and much of the workforce are already in place. In that setting, the marginal dollar buys tools and the relevant delay is procurement, installation and qualification.

The longer clock starts when a company begins a greenfield site. Construction, utility connections, cleanroom systems, equipment installation, process qualification and hiring all sit between the announcement and commercial output. A tool lead time captures only part of that sequence.

TSMC’s Arizona site makes the distinction visible. Its first fab began construction in June 2021 and started high-volume N4 production in the fourth quarter of 2024. TSMC says the structure of its second Arizona fab was completed in 2025, while N3 volume production is targeted for the second half of 2027. Finishing the building is not the same as finishing the capacity.

Intel’s Fab 52 tells a similar story. Intel broke ground on its two-fab Arizona expansion in September 2021. Fab 52 was fully operational in October 2025 and was preparing to reach high-volume Intel 18A production by year-end. The elapsed time was about four years.

Samsung and Micron provide the forward-looking observations. Samsung dates the groundbreaking for its first Taylor fab to 2022. On its first-quarter 2026 earnings call, Samsung said the fab would start operations in 2026 and commence mass production in 2027. I use the 2027 production milestone so the comparison stays consistent. Its second Taylor fab is expected to begin construction by the end of 2026 and target mass production in 2030. Micron formally announced the start of construction on its Boise memory fab in October 2023 and schedules initial DRAM output for 2027.

Why the dates need caution

These milestones are not standardized. A groundbreaking ceremony, the start of continuous construction, structure completion, equipment move-in and volume production are different events, but companies do not always report each one.

Micron is the clearest example. It held a Boise groundbreaking in 2022, then issued an October 2023 release titled “Micron Initiates Construction on Leading-Edge Memory Manufacturing Fab.” I used the later date because it is the company’s explicit construction milestone. Using the ceremony instead would lengthen the same project’s lag by about a year.

Samsung reports some milestones only by year. I placed those dates at the middle or stated boundary of the year and marked the resulting interval with a six-month tolerance. That is better than inventing a quarter, but it is still an estimate.

The sample also mixes two completed projects with three company schedules. Future delays would lengthen the latter observations. For that reason, 45 months should be read as a description of this small disclosed sample, not a forecast with false precision.

The capex-to-capacity ratio is harder to calculate

The same exercise exposed a second problem. To compare capital intensity, a project needs one budget and one planned wafer-start figure on the same basis. Only one row in the register meets that standard cleanly.

TSMC’s May 2020 Arizona announcement paired approximately $12 billion of spending with 20,000 wafers per month. That equals $600,000 of announced investment per monthly wafer start. The arithmetic is simple because both numbers describe the same fab in the same announcement.

More recent disclosures usually do not. Intel’s original $20 billion Arizona figure covered Fab 52 and Fab 62 together without a published wafer-start target for either. Micron’s roughly $15 billion Boise figure spans spending through the end of the decade. TSMC’s Arizona commitment now covers six logic fabs, two advanced-packaging facilities and an R&D center. None of those figures can be divided by a single fab’s capacity without adding assumptions that the companies did not disclose.

That limitation matters. A site-level investment number is useful for measuring the scale of a program. It is not automatically a measure of incremental wafer capacity.

What forecasters can take from the register

The practical lesson is modest. A capex announcement needs two labels before it can be used as a supply signal: whether the spending is greenfield or brownfield, and whether the disclosed dollars can be tied to a specific capacity figure.

For existing fabs, a roughly twelve-month equipment lag may still be a useful working assumption. For the five greenfield projects in this register, the company timelines are closer to four years from construction start to first output. Combining the two in one aggregate lag hides the difference.

The register is small, US-only and dependent on company disclosures. Its value is not a universal 45-month rule. Its value is showing which clock a forecast is actually using.

Nikhil Shah is a finance student at UT Austin’s McCombs School of Business. The underlying project register records the source, date precision and calculation for every observation.

Also Read:

Podcast EP362: An atomic layer in compute. A discussion of what can be built as graphene photonics scales with Cedric Huyghebaert

How TSMC Is Wiring the AI Era With Light

The Fab Is Not the Finish Line


A 0.42-Nanometer Breakthrough From TSMC Could Push Transistors Beyond Silicon

A 0.42-Nanometer Breakthrough From TSMC Could Push Transistors Beyond Silicon
by Daniel Nenni on 08-14-2026 at 8:00 am

A 0.42 Nanometer Breakthrough Could Push Transistors Beyond Silicon

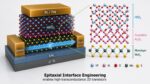
Researchers at National Yang Ming Chiao Tung University and TSMC Corporate Research engineered a 0.42-nanometer aluminum-oxide interface that protects electron transport in monolayer MoS₂ transistors while enabling strong gate control.

Silicon transistors are approaching physical limits that make each new generation harder to scale. Two-dimensional semiconductors such as monolayer molybdenum disulfide (MoS₂) offer a possible route forward because their channels can be only one atomic layer thick without losing useful electronic behavior. Their practical performance, however, has been constrained by a less visible component: the interface between the semiconductor channel and the gate dielectric.

A field-effect transistor uses a gate electrode to modulate current through a channel. Between the gate and channel lies an insulating dielectric. Reducing the dielectric’s equivalent oxide thickness, or EOT, strengthens the gate’s electrostatic control, helping suppress short-channel effects and lowering operating voltage. In conventional silicon technology, mature oxidation and deposition processes produce high-quality interfaces. Monolayer MoS₂ presents a different challenge. Its van der Waals surface lacks dangling bonds, so deposited dielectric materials do not readily nucleate into a uniform film.

Poor nucleation can create gaps, defects, charge traps, and local electrical disorder. These imperfections increase leakage and hysteresis and scatter carriers moving through the MoS₂. Engineers therefore face a difficult tradeoff: a thinner dielectric improves gate control, but aggressive dielectric deposition can degrade carrier mobility and erase the channel’s intrinsic advantages.

Researchers at National Yang Ming Chiao Tung University and TSMC Corporate Research addressed this problem by treating the interface as an engineered device layer rather than a passive boundary. They deposited an ultrathin epitaxial aluminum layer directly on chemical-vapor-deposition-grown monolayer MoS₂, then oxidized it to form approximately 0.42 nanometers of aluminum oxide. A high-κ hafnium oxide dielectric was subsequently deposited above this interfacial layer.

The oxidized aluminum performs two functions. First, it supplies a smooth, continuous surface on which hafnium oxide can grow uniformly. Second, it acts as an atomic-scale buffer, limiting detrimental interactions between the high-κ dielectric and the semiconductor. The approach preserves electron transport while enabling a dielectric stack thin enough for strong electrostatic coupling.

Using this structure, the team fabricated short-channel, top-gate MoS₂ transistors with an EOT of about one nanometer. Devices with channel lengths near 100 nanometers achieved maximum transconductance of 0.45 millisiemens per micrometer, together with low gate leakage and minimal hysteresis. Transconductance measures how effectively gate voltage changes channel current; a high value therefore indicates strong gate authority and useful drive performance.

The result is important not because 0.42 nanometers defines the transistor’s gate length, but because it is the thickness of the engineered aluminum-oxide interface. That distinction matters: the advance does not represent a complete 0.42-nanometer transistor. Instead, it removes a major obstacle to scaling the dielectric system used with atomically thin channels.

Manufacturability also strengthens the work’s relevance. Many high-performance demonstrations rely on small MoS₂ flakes mechanically exfoliated from bulk crystals. Here, the researchers used CVD-grown monolayer material, a method more compatible with large-area and potentially wafer-scale processing. Significant challenges remain, including uniformity, defect control, contact resistance, reliability, process integration, and reproducibility across full wafers.

Even so, the study reframes a central problem in post-silicon electronics. At atomic dimensions, device behavior depends not only on the properties of individual materials but also on how their electron states, defects, and bonding environments interact across boundaries. An interface only a few atoms thick can determine whether a promising semiconductor delivers laboratory mobility or useful transistor performance.

Further optimization could target subthreshold swing, threshold-voltage stability, and source-drain contacts, all critical to energy-efficient switching. The interface must also survive thermal processing and prolonged electrical stress. Meeting those requirements would determine whether the laboratory structure can become a repeatable manufacturing module for chips.

The broader lesson is that future scaling may depend as much on interface architecture as on discovering new channel materials. By combining monolayer MoS₂, a 0.42-nanometer interfacial oxide, and a high-κ gate dielectric, the researchers demonstrated unusually strong electrostatic control without sacrificing transport. That balance moves two-dimensional transistors closer to practical low-power logic beyond silicon.

You can read the full paper here.

Also Read:

Intel and TSMC Take Different Paths to High-NA EUV

The Difference Between TSMC CoWoS-S and CoWoS-R

TSMC CoPoS Versus Intel EMIB Semiconductor Packaging

The Silicon Shield Has Never Been Stronger!


Intel and TSMC Take Different Paths to High-NA EUV

Intel and TSMC Take Different Paths to High-NA EUV
by Daniel Nenni on 08-07-2026 at 8:00 am

Intel TSMC HNA EUV 2026

Intel and TSMC are pursuing the same objective—manufacturing smaller, faster, and more energy-efficient semiconductors—but they have adopted different strategies for advanced lithography. Intel moved early to develop High-Numerical-Aperture Extreme Ultraviolet lithography, commonly called High-NA EUV, while TSMC has continued extending conventional EUV for its latest production processes. Their choices reflect different technology roadmaps, manufacturing priorities, and assessments of cost and risk.

Conventional EUV lithography uses 13.5-nanometer light and projection optics with a numerical aperture of 0.33. It has become essential to producing advanced logic chips because it can print much smaller structures than earlier deep-ultraviolet systems. High-NA EUV uses the same wavelength but increases the numerical aperture to 0.55. This enables approximately 1.7 times better resolution and may allow manufacturers to print some critical patterns with one exposure instead of using multiple patterning steps.

Intel became the first chipmaker to receive ASML’s commercial High-NA development system, the TWINSCAN EXE:5000. Installed at Intel’s research facility in Hillsboro, Oregon, the system has been used to develop processes, materials, masks, and design rules for future manufacturing technologies. Intel plans to introduce High-NA EUV into its Intel 14A process, following Intel 18A, while continuing to use conventional EUV and other lithography methods where they offer better economics.

The early commitment supports Intel’s effort to restore semiconductor process leadership and expand its contract-manufacturing business. High-NA EUV gives Intel an opportunity to build expertise before the technology becomes widely used, while potentially simplifying the production of its most critical chip layers. Replacing a multi-patterning sequence with a single exposure could reduce the number of masks and processing steps, shorten manufacturing cycles, and limit errors caused by aligning multiple patterns. Early adoption could therefore provide both a technical advantage and an important point of differentiation for Intel Foundry.

TSMC has followed a more cautious path. The company concluded that it could manufacture its A16 and A14 generations without immediately introducing High-NA EUV into volume production. Instead, TSMC has continued improving its established 0.33-NA EUV platform through better masks, photoresists, overlay control, computational lithography, process optimization, and design-technology co-optimization. Innovations such as nanosheet transistors, backside power delivery, and more flexible standard-cell architectures also provide performance and density improvements that do not depend entirely on lithographic resolution.

Economics are central to TSMC’s decision. High-NA systems are considerably more expensive than conventional EUV scanners and require a new supporting ecosystem. Their anamorphic optics also produce an exposure field only half the size of a conventional EUV field. That limitation can complicate the manufacture of large processors and AI accelerators, potentially requiring two patterns to be stitched together. High-NA also presents challenges involving depth of focus, photoresist performance, masks, inspection, metrology, and yield.

TSMC operates conventional EUV at enormous scale and has accumulated extensive experience maximizing its productivity and reliability. Continuing to use that mature infrastructure reduces execution risk and allows the company to obtain greater returns from its existing equipment.

For an ultra high-volume foundry serving many customers, a proven process with stable yields may be more valuable than introducing the highest-resolution tool before its financial benefits are clear.

This does not mean TSMC has rejected High-NA EUV. The company has purchased equipment for research and has begun developing High-NA lithography technology for future processes. TSMC is ASML’s largest customer, and TSMC CEO C.C. Wei has repeatedly said that the two companies are working closely on High-NA EUV.

TSMC has said that adoption will depend on measurable manufacturing benefits, technology maturity, and cost. Intel is similarly not replacing every conventional EUV exposure with High-NA; it will use the new technology selectively on layers on internal products where its resolution creates sufficient value.

Bottom line: The difference is therefore primarily one of timing. Intel is accepting the cost and risk of being an early adopter in exchange for earlier learning and possible process leadership. TSMC is extending a mature technology while waiting for High-NA EUV to demonstrate stronger production economics. Both strategies may ultimately lead to High-NA manufacturing, but they represent distinct routes toward the next generation of semiconductor scaling.

We’ve discussed this extensively in the SemiWiki Forum, where several lithography experts have weighed in. As always, politically incorrect comments are welcome!

Also Read:

ASML High-NA EUV is Not Ready for High-Volume Production

Crossing the Yield Cliff: IDP V6 and the Future of Manufacturing Forecasting

Beyond Moore’s Law: High NA EUV Lithography Redefines Advanced Chip Manufacturing


Executive Interview with James Huang of AlChip

Executive Interview with James Huang of AlChip
by Daniel Nenni on 08-03-2026 at 2:00 pm

James Huang

I had a chance sit down with James Huang, Director of Engineering at Alchip Technologies, to discuss the company’s recent multi-die packaging achievements and learn about Alchip’s next steps in pushing the boundaries of innovation for next generation AI ASIC.

James is acknowledged as a leading light in advanced node ASICs, based on his 25 years of SoC design and implementation experience. Prior to Alchip, he held key engineering and technical management positions at Simplex Solutions and Cadence Design Systems, Inc.

AI and HPC designs are pushing advanced packaging into the mainstream. From Alchip’s perspective, what is driving customer demand for TSMC CoWoS-based ASIC solutions now?

AI has fundamentally changed the design priorities for advanced silicon. A few years ago, advanced packaging was viewed as an optimization for a limited number of high-end applications. Today, it has become an architectural requirement for many AI and HPC designs.

The primary reason is that compute performance is no longer scaling fast enough on its own. Our customers tell us they need to combine multiple compute chiplets with HBM and high-speed I/O, while staying within practical limits for power, yield, and manufacturability. CoWoS provides a mature platform for achieving that level of integration.

Another important trend is that more companies, including hyperscalers and AI startups, are developing custom silicon. They are looking for differentiated architectures rather than off-the-shelf solutions. Advanced packaging is one of the key enablers of that differentiation.

For Alchip, this aligns closely with one of our core strengths: delivering complex custom ASICs through close collaboration with customers and ecosystem partners.

Where does Alchip see CoWoS fitting within the broader custom ASIC design flow, especially for AI accelerators, networking processors, and other high-performance designs?

We don’t see CoWoS as a packaging technology that is added at the end of a project. We see it as an integral part of the system architecture. For AI accelerators, networking processors, and HPC devices, packaging decisions influence many other aspects of the design, including die partitioning, floor planning, memory architecture, power delivery, thermal management, and verification.

That is why successful CoWoS programs require silicon and package co-design from the earliest planning stages. Our engineering teams work closely with foundry, packaging, IP, and EDA partners to ensure these decisions are made holistically, rather than sequentially.

Alchip has experience with both CoWoS-S and CoWoS-R. Can you summarize the company’s track record with these technologies and the types of customer programs they have supported?

Over the past several years, Alchip has participated in multiple advanced-node ASIC programs using both CoWoS-S and CoWoS-R technologies across AI, HPC, and networking applications.

While we can’t discuss customer-specific projects, these engagements have helped us build deep experience in silicon-package co-design, HBM integration, power integrity, thermal optimization, and manufacturing collaboration.

Each successful project strengthens our internal methodologies and increases our confidence in supporting increasingly complex heterogeneous integration platforms.

For readers who follow advanced packaging closely, how would you compare the design considerations for CoWoS-S versus CoWoS-R? Where does each technology tend to fit best?

These technologies address different optimization points:

CoWoS-S is based on a silicon interposer. It offers the highest interconnect density and is optimized for bandwidth-intensive applications, such as AI training accelerators with multiple HBM stacks.

CoWoS-R uses redistribution layers. It provides greater flexibility and cost advantages for designs that do not require ultra-high routing density.

Rather than viewing them as competing technologies, we see them as complementary options. The optimal choice depends on the device architecture, bandwidth requirements, package size, and cost objectives.

What are the most important front-end design decisions that influence success in a CoWoS-based ASIC program?

One of the most important lessons we have learned is that architectural decisions made early in the project have a disproportionate impact on overall program success.

These decisions include chiplet partitioning strategy, HBM organization, die size optimization, power budgeting, and package selection.

Each of these choices influences yield, manufacturability, verification complexity, and ultimately time-to-market.

Investing sufficient effort during the architecture phase can significantly reduce downstream design iterations.

What are the key architectural tradeoffs designers should evaluate when considering chiplet partitioning and memory integration?

There is no single optimal partitioning strategy.

Customers need to balance multiple considerations, including bandwidth versus latency, die size versus yield, process-node optimization, power efficiency, and package complexity.

Similarly, memory integration should be evaluated as part of the overall system architecture, rather than as an isolated component.

Our role is to evaluate these tradeoffs objectively and identify the solution that best fits the customer’s product goals.

What are the major power-delivery challenges in large CoWoS designs today?

Power density continues to increase rapidly, particularly in AI accelerators.
Today’s large multi-chip packages require careful coordination across silicon, package, and board design to maintain stable power delivery, minimize IR drop, and preserve signal integrity.

One trend we see clearly is that power delivery is becoming a system-level challenge, rather than only a chip-level challenge.

This reinforces the importance of cross-domain collaboration throughout the design process.

Thermal performance is another major design constraint. How early does thermal analysis begin, and what tradeoffs does it create in die placement, floor planning, package selection, and system-level design?

Thermal considerations should be addressed much earlier in the design process than many people think.

For advanced AI ASICs, thermal analysis starts during architectural planning because chiplet placement, high-bandwidth memory arrangement, power distribution, and package selection all strongly influence the cooling strategy. At this stage, engineers can evaluate how each architectural choice affects heat generation, heat movement through the package, and heat removal at the system level.

Waiting until physical implementation to address thermal issues often leads to costly redesigns.

Early thermal co-analysis enables more balanced tradeoffs among performance, manufacturability, reliability, and system-level cooling requirements.

What key verification challenges are unique to CoWoS designs?

Verification complexity increases significantly in heterogeneous multi-die systems compared with traditional single-die implementations.
In CoWoS-based designs, verification extends beyond silicon functionality. It must also account for interactions across die-to-die interfaces, package behavior, power delivery, thermal conditions, and system-level operating requirements.

The industry is moving toward more integrated verification methodologies that evaluate silicon and package behavior together, rather than independently.

Beyond design, successful CoWoS programs depend on manufacturing and supply-chain execution. What issues are most critical, particularly around capacity, yield, test strategy, and production ramp?

CoWoS programs require close coordination across multiple ecosystem partners, including foundry, packaging, memory, test, and assembly resources.
Key considerations include packaging capacity, HBM availability,manufacturing yield, test strategy, production scheduling, and ramp execution.

Successful execution depends not only on technical excellence, but also on disciplined program management across the entire supply chain.

This is an area where experienced ASIC service providers can create significant value for customers by helping align technical requirements, partner schedules, supply availability, and production milestones.

Without discussing customer-specific programs, what opportunities does Alchip see for CoWoS-L?

CoWoS-L represents another important step in heterogeneous integration.
As AI systems continue to scale, customers will need larger packages, higher interconnect density, and greater flexibility in integrating multiple functional chiplets.

We believe CoWoS-L will support new classes of AI and HPC systems that require higher levels of scalability than current packaging technologies can efficiently provide.

Alchip is actively preparing its design methodologies to support these future architectures.

Looking ahead, how does Alchip expect CoWoS-S, CoWoS-R, and CoWoS-L to evolve? As AI ASICs move to larger die, more chiplets, higher HBM capacity, and more demanding performance-per-watt targets, how should customers think about choosing among these options?

We expect CoWoS-S, CoWoS-R, and CoWoS-L to coexist because each addresses different design and market requirements.

Future AI ASICs will require more chiplets, higher HBM bandwidth and capacity, heterogeneous process technologies, more sophisticated power delivery, and stronger silicon-package co-optimization.

As these requirements increase, designers are unlikely to converge on a single packaging technology. Instead, they will select different CoWoS options based on their architecture, bandwidth requirements, package size, power objectives, manufacturability needs, schedule, and cost targets.

From Alchip’s perspective, the goal is not to promote one packaging technology over another. It is to help designers evaluate and implement the solution that delivers the best balance of performance, manufacturability, schedule, and total system cost.

Also Read:

Alchip Accelerates on AI ASIC Demand

AI Chip Design Moves Beyond Monolithic Silicon with Alchip 3DIC

Alchip’s Leadership in ASIC Innovation: Advancing Toward 2nm Semiconductor Technology